How to Engineer Autonomous RAG Pipelines for High-Volume Enterprise Content Marketing
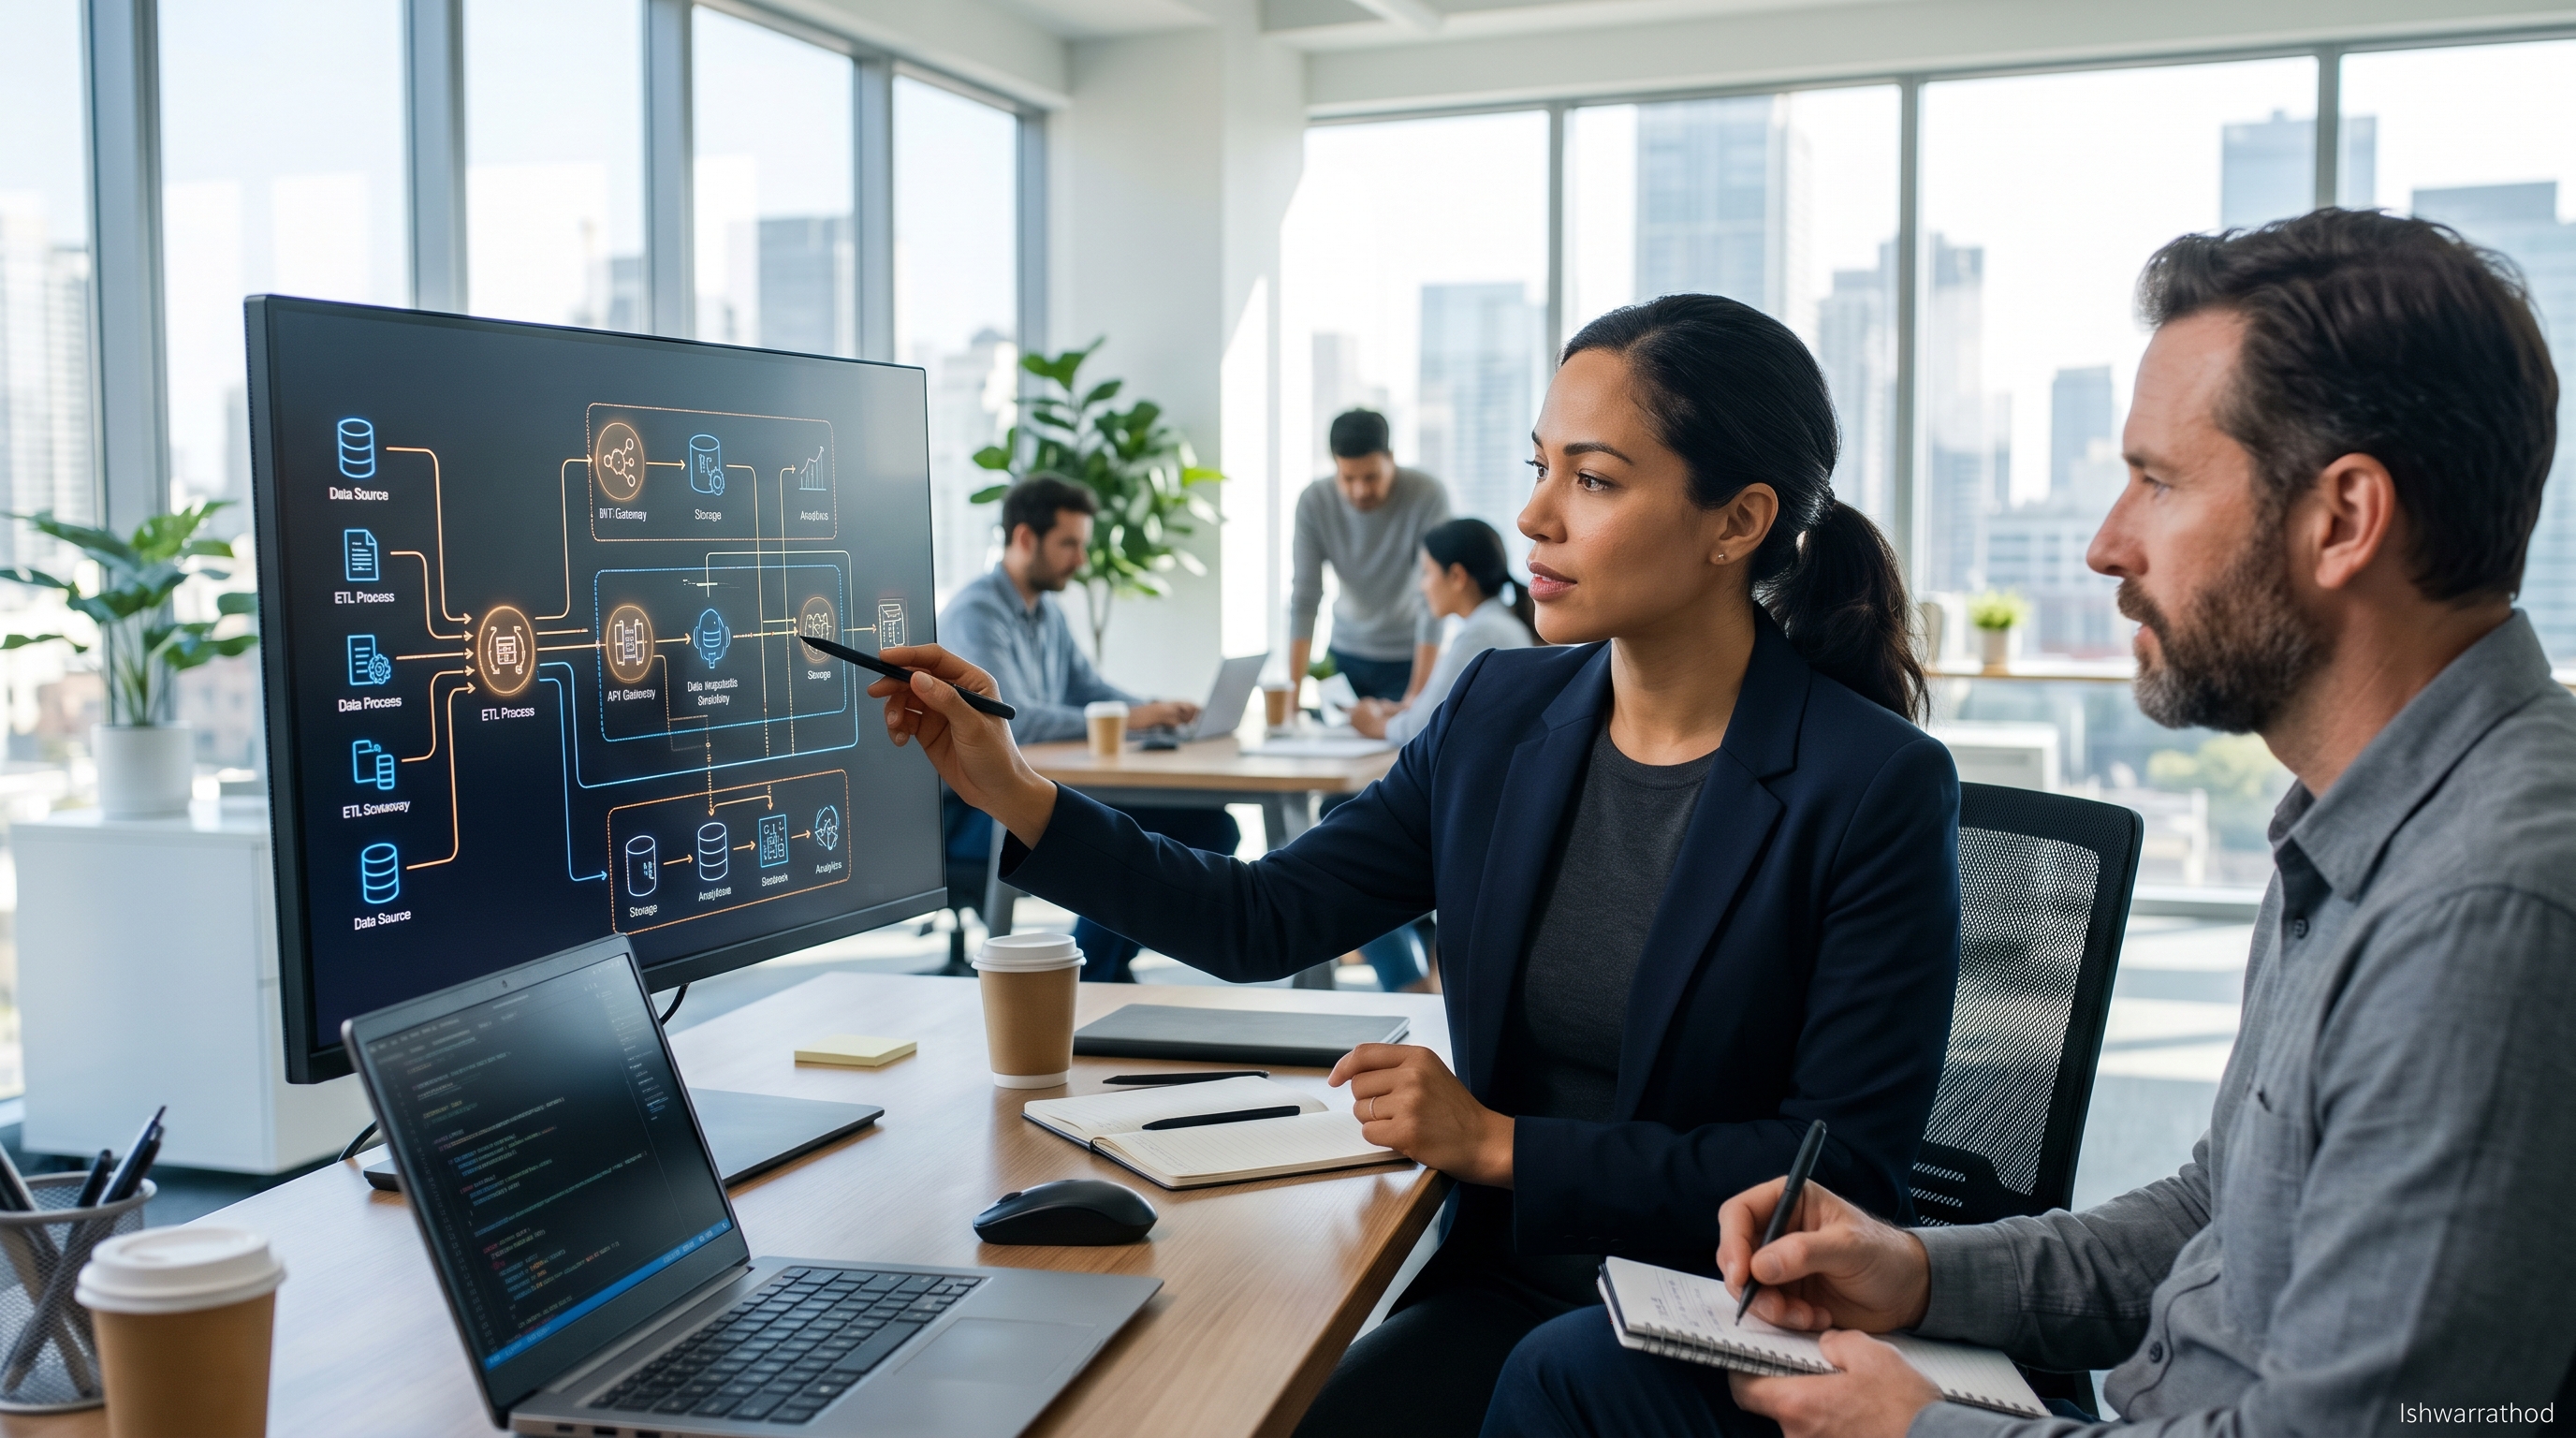
Scaling enterprise content without destroying quality or burning out your engineering team isn't just a goal—it's a critical survival metric for modern business. By building an autonomous Retrieval-Augmented Generation (RAG) pipeline, your content operations can stream hyper-accurate, context-aware articles and whitepapers at scale without human bottlenecks. Here is your step-by-step technical and strategic framework to architect a production-grade RAG pipeline tailored for high-volume enterprise engines.
The Scaling Trap in Enterprise Content Operations
Let's be honest: standard generative AI workflows break down the moment you scale beyond twenty complex articles a week. Hallucinations start creeping into brand messaging, outdated product specs get quoted, and your rankable content devolves into generic fluff that no search engine or human reader respects.
If you've ever struggled with keeping a enterprise content engine accurate while pushing for rapid market reach, you know the pain. The solution isn't writing better system prompts or hiring fifty freelance editors to review AI outputs. The real fix is engineering an autonomous Retrieval-Augmented Generation (RAG) pipeline designed specifically for enterprise brand intelligence.
For any enterprise business competing in dynamic markets like India or global tech hubs, moving from manual content production to an engineered RAG workflow changes the economics of digital marketing entirely. You stop trading quality for velocity.
Rethinking RAG: From Basic Q&A to Autonomous Content Engines
Most developers build naive RAG systems: dump PDFs into a vector database, run a simple similarity search, and pass top matches to a large language model (LLM). That setup works fine for a simple customer support chatbot, but it fails miserably for enterprise content marketing.
High-volume content creation requires context awareness, style governance, real-time factual accuracy, and automated self-correction loops. Here is the reality: naive RAG retrieves irrelevant text fragments because semantic similarity doesn't always equal context relevance for long-form publishing.
Think about it. A blog post needs narrative structure, internal links, brand voice guidelines, and current industry statistics. An autonomous RAG pipeline treats content creation as an orchestrated workflow of specialized agents, dynamic document retrieval systems, and real-time evaluation layers.
Architectural Blueprint of an Autonomous Content RAG Pipeline
To run a high-performing autonomous system, you need to break down your pipeline into five modular stages. Each stage operates independently while feeding state updates into an orchestrator.
1. Dynamic Ingestion & Semantic Chunking
Forget fixed token-length chunking (like standard 512-token splitters). Fixed chunks slice apart tables, code snippets, and structured arguments, rendering retrieved context useless for high-quality drafting.
- Semantic Document Splitting: Break content along natural semantic boundaries—such as H2 headers, bullet lists, or specialized code structures.
- Context Enrichment at Ingestion: Inject parent metadata directly into child chunks. Every chunk must carry metadata tags such as target audience, buyer journey stage, publishing date, and core subject categories.
- Knowledge Graph Pairing: Combine standard vector embeddings with a Graph Database (like Neo4j) to track relationships between entities, product specs, and core business concepts.
2. Hybrid Retrieval with Dynamic Re-Ranking
Relying solely on vector search leads to poor retrieval accuracy when exact terms matter (such as product names or pricing details). Combine vector similarity with keyword-based sparse search.
- Hybrid Search (BM25 + Vector Embeddings): Run parallel sparse and dense searches to capture both conceptual context and explicit keyword matches.
- Cross-Encoder Re-Ranking: Pass retrieved candidates through a re-ranker model (such as Cohere Rerank or BGE-Reranker) to score context based on dynamic prompt relevance rather than pure distance metrics.
3. Multi-Agent Drafter and Evaluator Nodes
What does this mean for you in practice? Instead of making a single LLM call to draft an entire post, orchestrate a graph of specialized agents (using frameworks like LangGraph or AutoGen):
- Outline Agent: Analyzes user intent, target keywords, and competitor SERPs to generate a detailed content schema.
- Researcher Agent: Queries your hybrid RAG system for internal brand knowledge, research papers, and case studies.
- Writer Agent: Drafts individual sections sequentially, pulling specific background context from the Researcher Agent.
- Critic/Evaluator Agent: Scores the draft against criteria like factual alignment with retrieved sources, brand tone, and target keyword density.
Pro-Tip: Stop using default vector cosine similarity search alone for enterprise business content. Implement a reciprocal rank fusion (RRF) algorithm combining sparse keyword search with dense embeddings, followed by a dedicated cross-encoder re-ranking step. This setup increases accurate context retrieval precision by over 45% in complex, domain-specific content engines.
Implementing Autonomous Self-Correction and Guardrails
An enterprise business cannot afford reputational risk caused by unvetted AI hallucinations or inaccurate claims. To make your RAG pipeline truly autonomous, you must embed automated self-correction loops directly into generation nodes.
When the Critic Agent flags a factual claim in the generated text that lacks a direct match in the retrieved context chunks, the pipeline automatically triggers a targeted sub-query back to the vector store. If the claims cannot be validated against your verified internal knowledge base, the system strips out the ungrounded statement or flags the paragraph for human review.
By shifting human involvement from drafting to targeted exception-handling, your editorial team spends time managing strategy rather than rewriting poor outputs. This operational pivot allows a small content team to maintain publication standards across hundreds of pieces per month.
Measuring ROI and Operations in High-Volume Contexts
When deploying this infrastructure for a high-volume enterprise business, focus on metrics that impact both cost efficiency and organic search performance:
- Retrieval Precision at K (P@K): Measures whether top-retrieved context chunks actually contain the factual answers needed for drafting.
- Hallucination Rate: Percentage of output assertions that fail source-grounding checks. Target an enterprise threshold under 1%.
- Time-to-Publish Velocity: Hours saved per asset, moving from conceptual brief to live publication.
- Organic Search Visibility: Keyword ranking health, answer engine optimization (AEO) indexing, and impression growth across engines like Google, Perplexity, and ChatGPT.
Frequently Asked Questions
What is an autonomous RAG pipeline in content marketing?
An autonomous RAG (Retrieval-Augmented Generation) pipeline is an automated system that retrieves dynamic facts, case studies, and brand guidelines from a private database, passing that exact context to AI agents that draft, evaluate, and edit high-volume marketing content with minimal human intervention.
How does dynamic re-ranking improve enterprise content accuracy?
Dynamic re-ranking uses a cross-encoder model to re-evaluate context chunks fetched by vector search. It scores retrieved fragments based on actual semantic relevance to the specific section being written, filtering out irrelevant chunks before they reach the drafting model and drastically lowering hallucination rates.
What vector databases work best for high-volume enterprise RAG engines?
Production-ready choices include Qdrant, Pinecone, and Weaviate for cloud-native setups, or Pgvector (PostgreSQL) for teams seeking integrated data infrastructure. The optimal choice depends on query volume, metadata filtering needs, and latency requirements.
Building the Future of Enterprise Content Scaling
Bottom line: Continuing to rely on standard manual workflows or naive AI prompts for enterprise publishing guarantees diminishing returns. Engineering an autonomous, graph-driven RAG architecture turns content operations into a scalable technical asset that powers revenue growth.
If you are ready to modernize your content architecture, accelerate publishing output, and build industry-leading authority across organic search and AI answer platforms, partner with experts who understand both software engineering and organic search strategy. Learn more about advanced enterprise strategies with Ishwarrathod.
Want to Scale Your Core Performance Metrics?
Let's construct multi-channel algorithmic acquisition pipelines explicitly for your business operations.
Initialize Consultation Session →